Ask
suppose we start with a set of seed queries. what can go wrong with this?
Prompt
wands dataset is in ../wands. Build a search system over wands data - given any query, returns ranked list of products.
Can a coding agent build product search on its own? Walk through one working session step by step: the prompt, the checks, and where plain grep beat hybrid search.
suppose we start with a set of seed queries. what can go wrong with this?
wands dataset is in ../wands. Build a search system over wands data - given any query, returns ranked list of products.
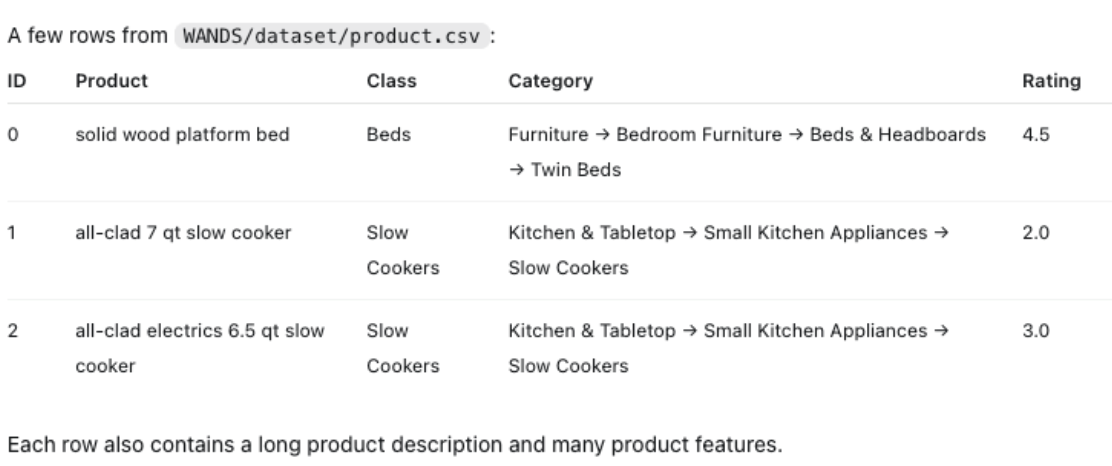
other fields too, including Product Description
zachary 72.5
comfortable accent chair
small space dining table and chairs sets
ranked product IDs
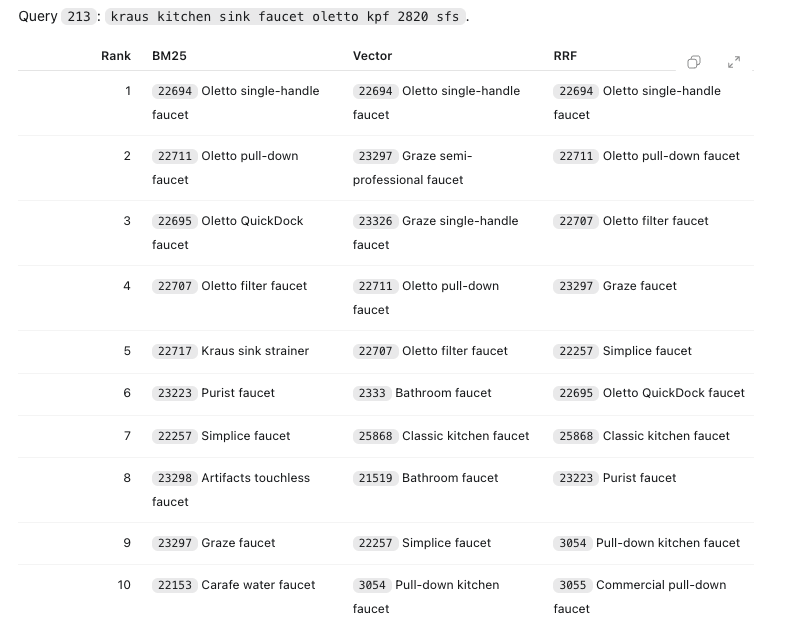
compare different bridges
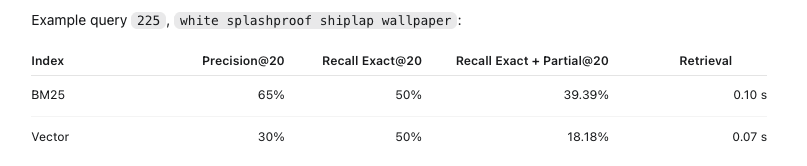
recall@k, precision@k
when is one ranked list better than another?
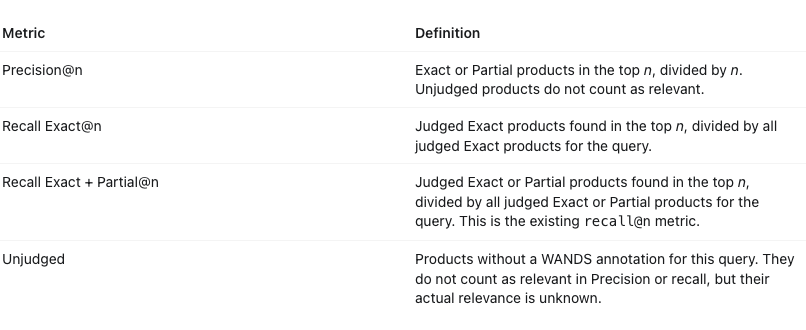
labels are EXACT, PARTIAL, UNJUDGED
recall-EXACT@k tells us if the exact match is there in top-k
use ripgrep (rg) to search over csv dataset directly (call this rg-rank strategy)
match each keyword against product title, description etc
but results don't have score!
need to score results for ranking
Rank candidate products with the manual field-weighted scoring rule.
Each distinct query word is worth three points in product_name, two points in product_class, and one point in product_description
rg-rank finds at least one in top-5
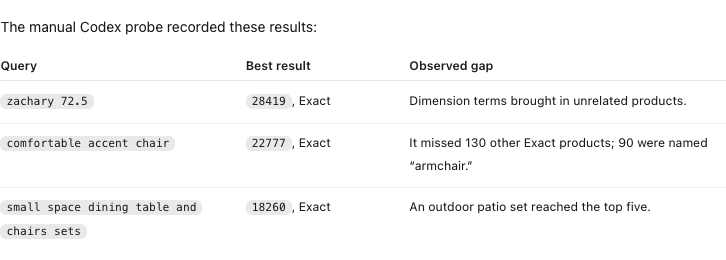
can we do better?
let's expand query = "comfortable accent chair accent chairs"
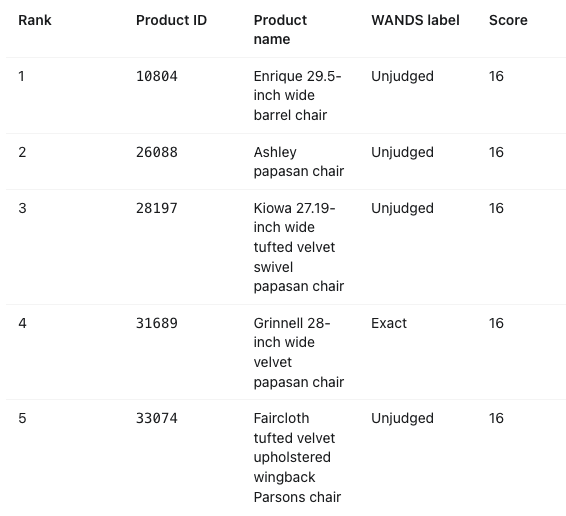
doesn't improve Recall-Exact@5
comfortable accent chair armchair
Adding all class terms made results worse
Adding armchair did not change the top five because none of the first five products contains armchair. It improved Recall Exact@20 from 1.53% to 3.82%
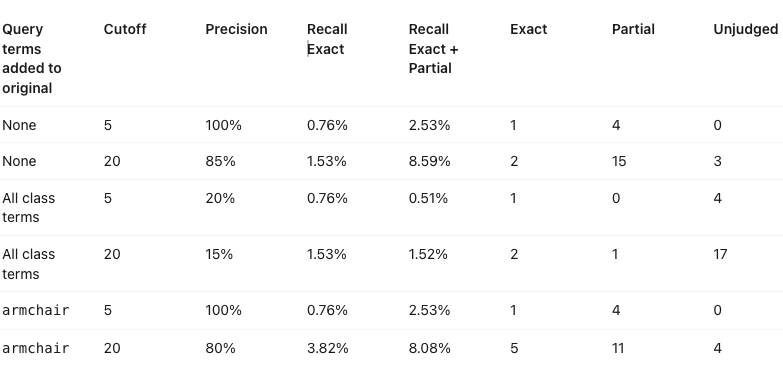
bottomline = query expansion does not improve rg-rank
agent can't do BM25/dense search natively. needs tools!
ask agent to implement BM25, dense and fusion search modules
which product fields to match with? 2 options. product_name, product_description. combine them.
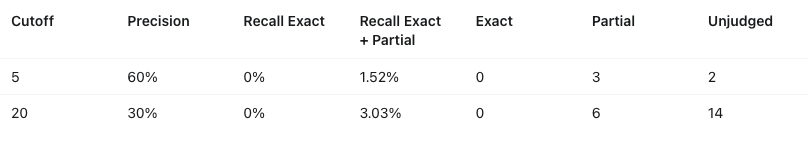
recall Exact is 0% at k = 20
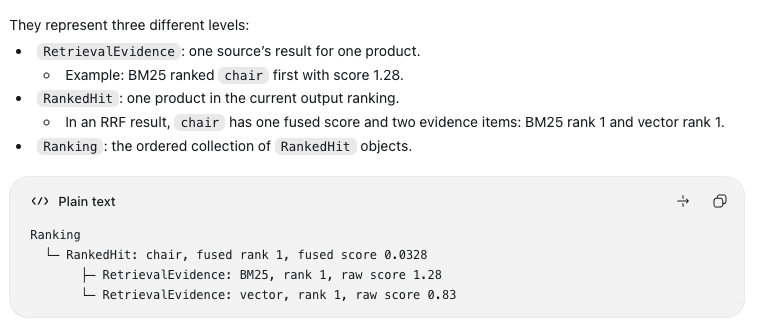
BM25 did retrieve Exact product 29995 at rank 16. Vector retrieval did not return it in its top 20. Fusion moved 29995 to rank 24 because it had evidence from only BM25, while products supported by both sources ranked higher.
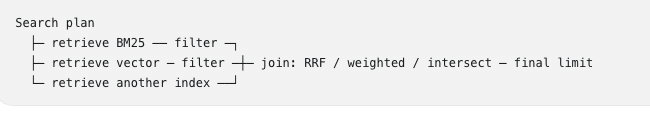
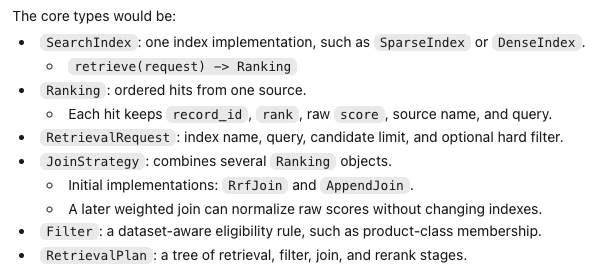
key rrf data structures for provenance
making implementation changes along with discovery, makes it hard to strategize
Let's sample some queries
Use only product name for bm25/vector/hybrid
query - small wardrobe grey. vector > bm25
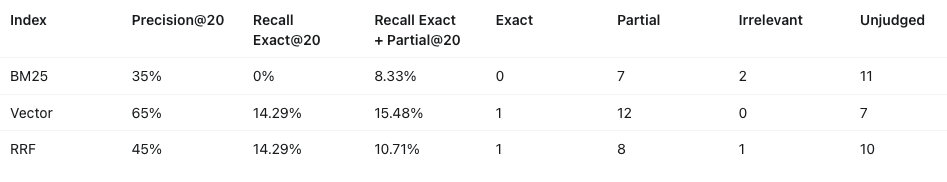
query - 7qt slow cooker. hybrid better than rg-rank at k=20. hybrid beats either (bm25/dense). Large k=100 => any strategy works.
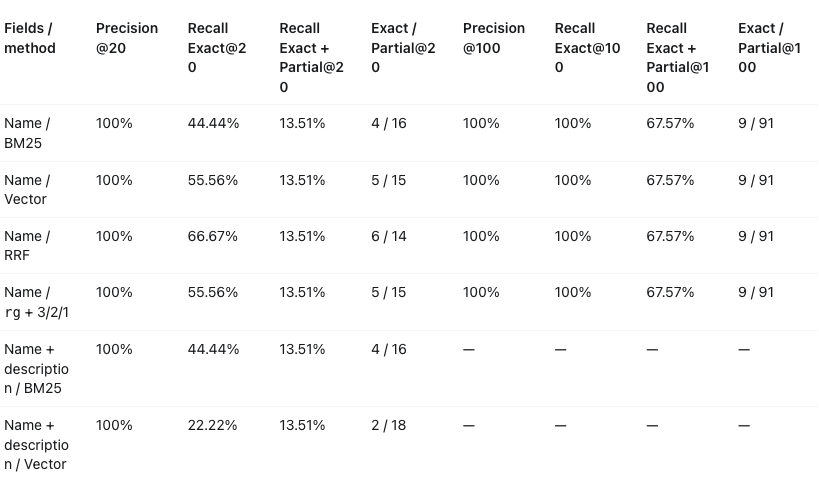
query - white bathroom vanity black hardware. no strategy works!
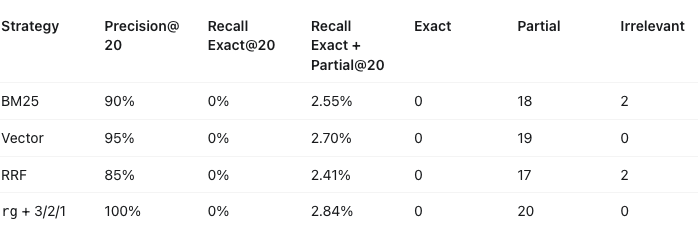
rg-rank is pretty good
rg-rank is pretty good
outperforms bm-25+vector hybrid for many queries
to explore - when is rg-rank better? when is bm25-dense hybrid better?
build search with codex/claude? start with an initial bundle of search tools. Implementing vs Strategizing simultaneously can get confusing.