OpenAI GPT-Live-1 vs Nemotron VoiceChat
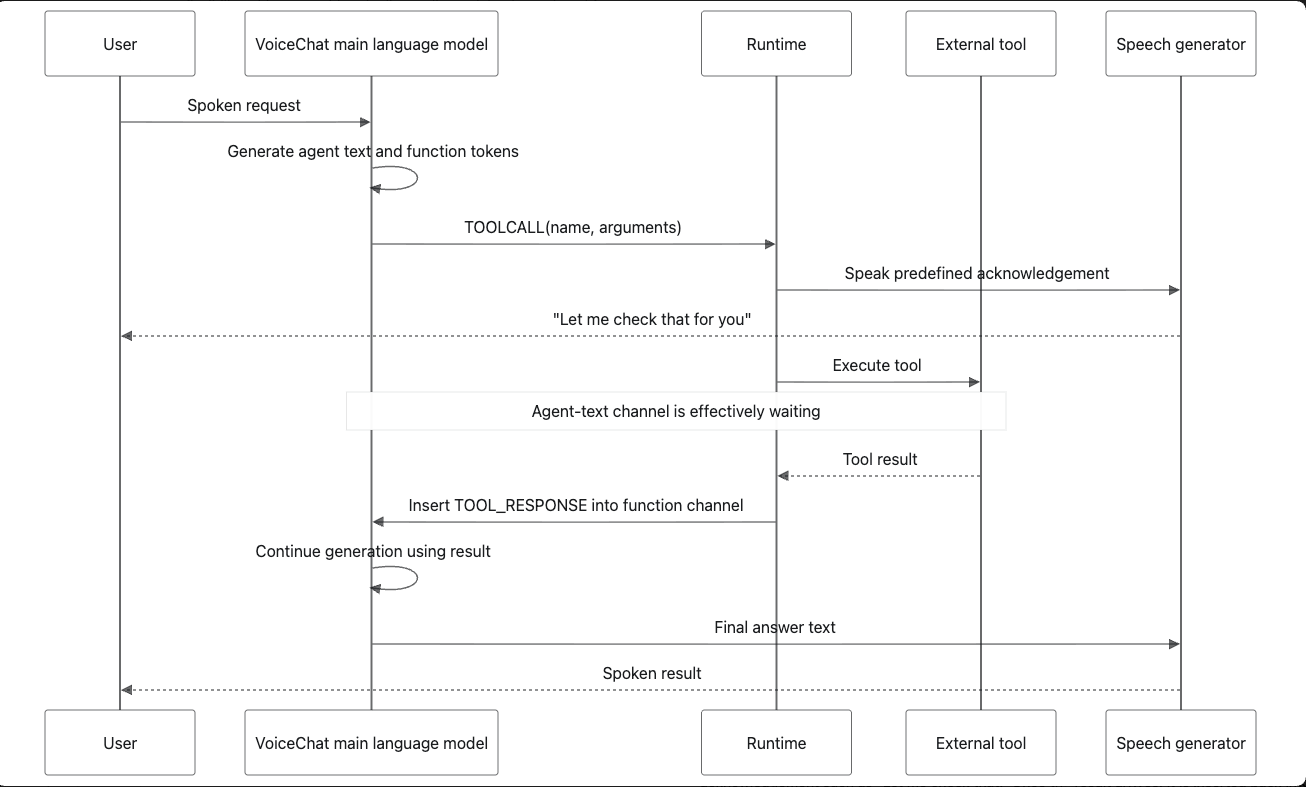
A live voice agent does two jobs at once: run the conversation in real time (listen, decide when to speak, handle interruptions) and solve the user’s task, which may mean slow tool calls and reasoning. GPT-Live-1 and Nemotron VoiceChat are both full duplex models, but they split those jobs differently.
Takeaways
- GPT-Live-1 hands slow work to a separate backend model, a vertical cascade. The conversation keeps going while the job runs, and interrupting the talk does not cancel the job.
- VoiceChat keeps tool calls inside one model. The conversation waits for the tool behind a filler like "Let me check that", and the user cannot barge in meanwhile.
- The open question: can a single live model handle background jobs too, and is that better than a vertical cascade?
Have a system that needs a second opinion?